

Overview
Supermicro has made a number of submissions to the MLPerf Inference 6.1 benchmark program, demonstrating that the NVIDIA HGX B300 system with eight NVIDIA Blackwell Ultra GPUs connected with NVIDIA NVLink for LLM inference. MLPerf Inference 6.1 includes four LLM benchmarks.
These LLMs are strong proxies for AI workloads in the data center, supporting chatbots, image queries, reasoning, summarization, and interactions with many AI agents.
Test Systems
Supermicro produced these results using the following systems, each configured with 8x NVIDIA Blackwell Ultra GPUs connected with fifth-generation NVIDIA NVLink and features an aggregate of 2.1TB of HBM3e memory:
- Supermicro SYS-822GS-NB3RT with Intel® Xeon® 6 CPUs
- Supermicro AS-8126GS-NB3RT with AMD EPYC™ 9005 Series CPUs
Benchmark Results
| Benchmark | Tokens/second (rounded) | Model |
Total Parameters |
Active Parameters |
| Reasoning |
Server: 67,000 Offline: 70,000 |
DeepSeek-R1 | 671B | ~37B |
| Vision-language |
Server: 112 queries/sec Offline: 129 samples/sec |
Qwen3-VL-235B-A22B | 235B | 22B |
| LLM reasoning/coding, RAG query generation |
Server: 107,000 Offline: 109,000 |
GPT-OSS-120B | 117B | 5.1B |
| Question Answering |
Server: 110,000 Offline: 111,000 |
Llama 2 70B | 70B | 70B |
MLPerf Inference v6.1 data center benchmarks highlight the importance of serving LLMs to AI agents running everywhere. Supermicro tested Mixture-of-Experts (MoE) models, including DeepSeek, Qwen, and GPT-OSS, where the full set of experts is loaded into GPU memory but only a subset of experts is activated for each token, as well as the Llama dense model, where every parameter is activated for every token. Together, these benchmarks provide a representative mix of the model types used for LLM serving in the data center today. Across all of them, Supermicro’s NVIDIA HGX B300 server demonstrated very high inference performance.
Comparing NVIDIA Blackwell Ultra Platforms
MLPerf Inference v6.1 published results for a wide range of GPU systems. Most of these results are based on 8x GPU configurations, so it’s useful to compare three of these systems:
- NVIDIA GB300 NVL72, using 8x Blackwell Ultra GPUs
- NVIDIA HGX B300 8-GPU System
- PCIe GPU System with 8x NVIDIA RTX PROTM 6000 Blackwell Server Edition GPUs
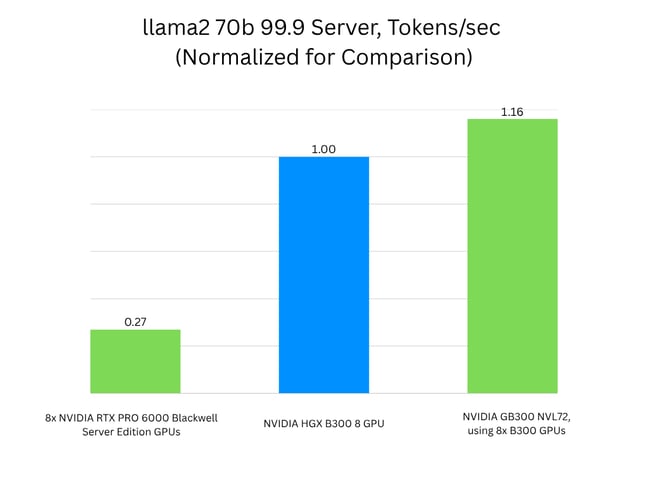
The chart shows relative performance for the Llama 2 70B benchmark, normalized to tokens per second, for this specific 8-GPU inference configuration. The NVIDIA GB300 NVL72 shows an edge here because its rack-scale design runs each Blackwell Ultra GPU at a higher power envelope, giving it greater per-GPU compute throughput — one data point for one model at this scale. GB300 NVL72's full-rack architecture is built for the industry's largest and most demanding workloads, including training and inference for frontier-class models with trillions of parameters, where its scale offers a clear advantage, at the cost of a full 72-GPU rack requiring over 132kW of power and liquid cooling.
Built for Flexible, Scalable Deployment
Many existing data centers have only air cooling with constrained power budgets. NVIDIA HGX B300 8-GPU systems and NVIDIA RTX PRO Servers provide flexibility and scalability, especially for inference-focused AI infrastructure.
Supermicro offers the full spectrum of NVIDIA Blackwell and NVIDIA Blackwell Ultra optimized systems, NVIDIA-Certified systems, combined with NVIDIA Grace CPU, AMD EPYC, or Intel Xeon CPUs, supported with air-cooling or liquid-cooling.
Deploy AI Infrastructure Faster with Supermicro DCBBS
Turning strong benchmark results like these into production AI infrastructure is where many enterprises get stuck, weighing GPU, CPU, networking, power, and cooling choices against their own workloads and timelines. Supermicro’s Data Center Building Block Solutions® (DCBBS) address that challenge directly, pairing validated, workload-optimized building blocks with the deployment experience needed to bring them online quickly. With deep expertise across NVIDIA Blackwell and Blackwell Ultra platforms, air- and liquid-cooled system designs, and a broad range of CPU and GPU configurations, Supermicro helps enterprises identify the right AI infrastructure for their needs and deploy it in the fastest way possible.
Looking ahead, NVIDIA's MLPerf Inference v6.1 submission gave the industry an early look at the next-generation Vera Rubin platform — a substantial leap in scale and capability for AI infrastructure. As NVIDIA Vera Rubin platform becomes available across the ecosystem, Supermicro's DCBBS approach is designed to evolve alongside it, helping enterprises navigate this next tier of AI infrastructure and bring it into production.
Learn more: Supermicro AI Server Solutions
Subscribe to Data Center Stories
By clicking subscribe, you consent to allow Supermicro to store and process the personal information submitted above to provide you the content requested.
You can unsubscribe from these communications at any time. For more information on how to unsubscribe, our privacy practices, and how we are committed to protecting and respecting your privacy, please review our Privacy Policy.